Qwen is Alibaba's family of AI models, and Qwen4-Max is the newest and largest model in it, released on 16 November 2026. It costs USD 1.50 per million input tokens and USD 4.50 per million output tokens through the API. It is strong at agentic coding and legal agent work, trails Claude Opus 5.5 on most office tasks in Alibaba's overview, and suits businesses where cost per task matters more than the top score.
Below you will find what the model is, what the tests show, what it costs, and what a European business should check about data and privacy before using it.
What is Qwen4-Max?
Qwen4-Max is the largest model in Alibaba's Qwen4 series, built by the Qwen team. Alibaba calls it an AI teammate for work, creative work and research, designed for long tasks where the model uses tools on its own over many steps.
| Property | Qwen4-Max |
|---|---|
| Released | 16 November 2026 |
| Developer | Alibaba (Qwen team) |
| Model ID in the API | qwen4-max |
| Size | 2.4 trillion parameters in total, 71 billion active per token |
| Context window | 1 million tokens |
| Input | Text, images and video |
| Output | Text |
| Reasoning effort | low, high and xhigh (high is the default) |
| Compatibility | OpenAI and Anthropic APIs, tool calling, web search and structured outputs |
| Open weights | No. According to Alibaba, smaller Qwen4 models with open weights will follow |
Tokens are the word pieces a model reads and writes. 1 million tokens is roughly 1,500 A4 pages of text. Artificial Analysis estimates 1,475 pages for 984,000 tokens. Having 2.4 trillion parameters but using only 71 billion per token means the model is a Mixture-of-Experts model: only a small part of it works on each word, which Alibaba says lowers the cost of running it.
The model is available in QwenCloud through the API and the Token Plan subscription, and in Alibaba's own tools QwenWork and QwenStudio.
What is new compared with Qwen3.8-Max?
According to Alibaba, Qwen4-Max beats its predecessor on almost every test they ran, and uses fewer tokens doing so:
- New architecture. 25 percent fewer active parameters per token than Qwen3.8-Max, at the same total size.
- Fewer tokens per task. On Alibaba's own Work360 test the model uses about 35 percent fewer tokens at high effort and 24 percent fewer at xhigh. On the coding test Terminal-Bench 4.0 the reduction is about 49 and 48 percent.
- Lower cost per task. On Work360 the average cost per task fell from USD 4.43 to USD 1.67, a 62 percent drop. Alibaba has also cut API prices, most for cached input.
- Better results on work tasks. Work360 covers 721 professional fields. Qwen4-Max scored 52.69, against 47.74 for Qwen3.8-Max.
Work360 is Alibaba's own test, so these figures have not been checked by others.
Benchmarks: how good is Qwen4-Max?
Alibaba compares Qwen4-Max with its predecessor, Claude Opus 5.5 from Anthropic, GPT-6.1 Sol and GPT-6 Astra from OpenAI, and Kimi K3.1 from Moonshot. OpenAI has since released the successors to GPT-6 Astra and GPT-6.1 Sol, see GPT-6.2 Astra and Sol. Google followed with Gemini 4 Neon on 18 November. The figures below are from Alibaba's launch page. Some are taken from independent leaderboards, as Alibaba notes in its footnotes (AA-Briefcase and Automationbench-AA from Artificial Analysis, APEX-Agents from Mercor and HLAB-Vals from Vals). The rest are Alibaba's own measurements.
| Test (Alibaba's overview) | What it measures | Qwen4-Max | Qwen3.8-Max | Opus 5.5 | GPT-6.1 Sol | Kimi K3.1 |
|---|---|---|---|---|---|---|
| DeepSWE v1.1 | Agentic coding | 75.7 | 69.3 | 74.2 | 75.2 | 75.5 |
| Terminal-Bench 4.0 | Coding in the terminal | 48.5 | 38.9 | 59.6 | 56.1 | 67.2 |
| AA-Briefcase v1.1 (Elo) | Knowledge work with documents | 1,686 | 1,605 | 1,801 | 1,555 | 1,674 |
| JobBench | Real professional tasks | 68.5 | 65.3 | 75.4 | 66.2 | 61.2 |
| APEX-Agents v1.1 | Consulting and professional services tasks | 72.1 | 63.3 | 73.5 | 60.0 | 65.5 |
| HLAB-Vals-1.1 | Legal agent work | 21.3 | 15.4 | 9.2 | 6.3 | 11.7 |
| Automationbench-AA | Workflows in SaaS systems | 72.5 | 56.2 | 69.5 | 64.9 | 73.3 |
| Humanity's Last Exam | Very hard expert questions | 51.7 | 43.9 | 59.8 | 54.0 | 51.1 |
GPT-6 Astra is left out of the table but appears in the figure below. Higher is better in every row. Elo is a ranking where outputs are compared in pairs. What the tests measure and how to read them is explained in AI benchmarks explained.
The picture is clear: Qwen4-Max leads on agentic coding (DeepSWE), legal agent work (HLAB-Vals) and long tasks (Agents' Last Exam in the figure), and is near the top on automation in business systems. Claude Opus 5.5 is ahead on document work, professional tasks, consulting tasks (APEX-Agents) and the hardest expert questions. On terminal coding, Qwen4-Max is clearly behind all three competitors.
The full overview as Alibaba published it, with all 16 tests:
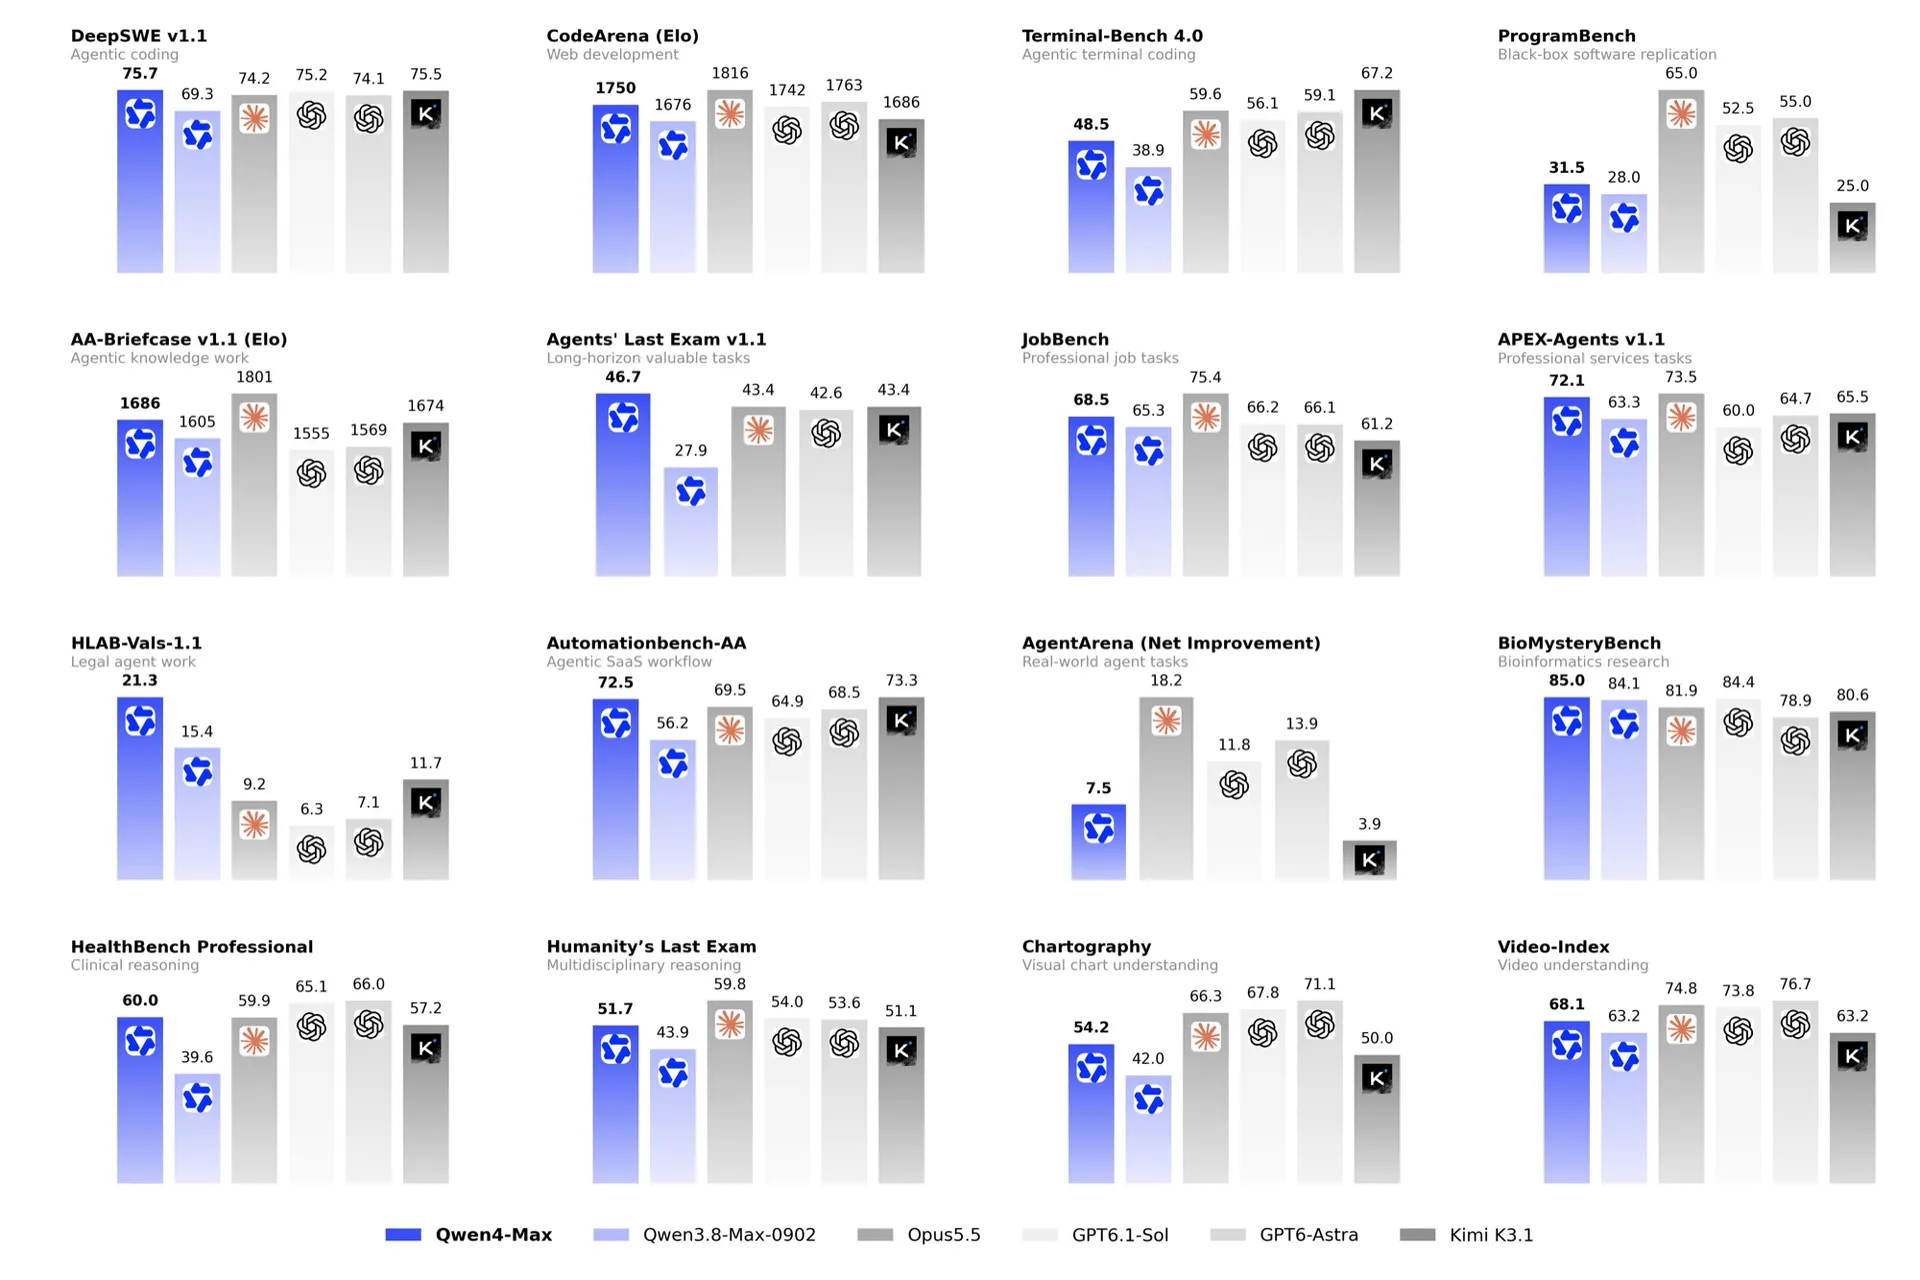
Source: Qwen team, Qwen4-Max launch page, 16 November 2026.
In its press release Alibaba also states that Qwen4-Max ranks 6th on Code Arena, a leaderboard where users vote on which model solved a coding task best.
What independent measurements say
Artificial Analysis had results on launch day. Qwen4-Max scores 43 points on its Intelligence Index, a composite of nine tests covering agentic coding, office automation, knowledge and physics. That puts it 38th of 81 models, slightly above the median of 41 for comparable models.
The same measurement shows two weaknesses. The model is verbose: it used 127 million tokens on the tests, against a median of 78.6 million. It is also slow, at 32.1 minutes per task against a median of 13.3.
What have people built with Qwen4-Max?
The examples below are published by Alibaba on the launch page, and we have found no independent verification of them.
| Who | What the model did, according to Alibaba |
|---|---|
| SANF and Pacific Union (car manufacturing) | Planned production lines, designed car parts and checked machining. Manual programming of one workpiece went from about 475 to 24 minutes |
| Alibaba Cloud | Optimised its own cloud resource scheduling and cut the cost of model calls for data annotation by 9 to 10 percent on average (the press release says 9, the launch page 10.42) |
| Research project on cooling for computer chips | Ran for 48 hours straight through four rounds of molecular design, synthesis and testing, and found a new coolant that was tested in the lab |
What the examples share is long tasks where the model works on its own with tools over many steps, in one of the examples with 90 MCP connections to financial data.
Qwen4-Max or Claude Opus 5.5: what is the difference?
Claude Opus 5.5 is the first competitor in Alibaba's overview, and the one we compare with here.
| Qwen4-Max | Claude Opus 5.5 | |
|---|---|---|
| Price in / out per million tokens | USD 1.50 / 4.50 | USD 4 / 20 |
| Intelligence Index (Artificial Analysis) | 43 points | 59 points |
| Cost per task in the index (Artificial Analysis) | USD 3.27 | USD 10.04 |
| DeepSWE v1.1, agentic coding (Alibaba) | 75.7 | 74.2 |
| JobBench, professional tasks (Alibaba) | 68.5 | 75.4 |
| Developer | Alibaba, China | Anthropic, USA |
Opus 5.5 gives better results on most office tasks. Qwen4-Max costs about a third per task. How Claude and ChatGPT compare in everyday use is covered in ChatGPT vs Claude.
If you are looking at other Chinese models, DeepSeek V4 and its pricing is the closest alternative we have written about.
How much does Qwen4-Max cost?
The prices are Alibaba's list prices in Model Studio for the Singapore (International) region, read on 17 November 2026.
| What | Price per million tokens |
|---|---|
| Input (up to 1 million tokens per request) | USD 1.50 |
| Output, with and without thinking | USD 4.50 |
| Input read from cache | USD 0.075 |
| Cache write, 5 minutes | USD 1.875 |
| Cache write, 1 hour | USD 3 |
The same price applies across the whole context window, so a long request costs the same per token as a short one. New users in the Singapore region get 1 million free tokens valid for 90 days.
The token price alone says little, because the model is verbose. Measure the cost per finished task on your own tasks before you choose.
Should your business use Qwen4-Max?
For most European businesses the answer is: test it first on well-defined tasks that involve no personal data.
| Task | Is Qwen4-Max a fit? |
|---|---|
| Agentic coding and automation in business systems, at high volume | Yes, worth testing. Low cost per task compared with Opus 5.5 and good results in Alibaba's tests |
| Legal review with an agent | Worth testing. Leads HLAB-Vals, but with low scores for every model |
| Document work, reports and customer writing | Opus 5.5 scored better in the same tests |
| Tasks with personal data or confidential information | Only after data processing and region are settled (see below) |
Check three things before you use the model through the API:
- Region and where inference runs. In Model Studio the region decides where data is stored, and a separate setting, the deployment scope, decides where the model computes. The Frankfurt region supports both the Global and the EU scope. The model page we read on 17 November listed the Global scope for Qwen4-Max. Alibaba describes only the region-bound scopes as geographically limited, so with Global the model may compute outside the EU. Check whether the EU scope is available for the model in Alibaba's documentation on regions before you send personal data.
- Data processing agreement. Alibaba is a Chinese company. Make sure the agreement states where data is stored and processed, and whether anything is transferred outside the EEA. What the GDPR requires when you adopt AI is covered in AI and the GDPR in Norway.
- Cost per finished task. Run the same tasks on Qwen4-Max and the model you use today, and compare cost and quality per finished task.
If you want to find out which tasks in your business suit a cheap model and which need a more expensive one, an AI consultant can go through the workflow with you. We also build the solutions, see AI development, and teach staff to pick the right model in our AI courses.
Sources
- Qwen team: Qwen4-Max: Your New Teammate Has Arrived, 16 November 2026 (architecture, Work360, token use, cost per task, benchmark overview, examples)
- Alibaba Cloud: Alibaba Unveils Qwen4-Max, press release 16 November 2026 (parameters, Code Arena, open weights)
- Alibaba Cloud Model Studio: qwen4-max, pricing and regions and deployment scope, read 17 November 2026
- Artificial Analysis: Qwen4 Max, read 17 November 2026 (Intelligence Index, cost and time per task, token use)
- Anthropic: pricing page, read 17 November 2026 (Claude Opus 5.5 pricing)